DiPLO: Self-distilled Diffusion Planning for Loco-manipulation
Preprint, arXiv 2026
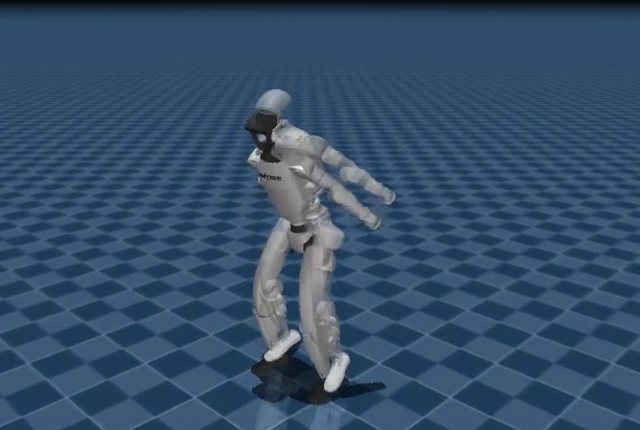
A diffusion planner generates whole-body robot and object motion, and a single tracking policy trained with RL executes it. The planner is pretrained on 2.7 minutes of retargeted human motion, expanded with sampling-based trajectory optimisation and symmetry augmentation. Self-Distillation Diffusion Policy Optimisation (SD:DPO) then removes its dependence on the retargeted reference motion, and Diffusion-Augmented PPO (DA:PPO), a maximum-entropy RL method for diffusion models, fine-tunes it against the frozen tracker. Task success on pick-carry-place rises from 45% for the pretrained planner to 99%, with state-history and goal conditioning only. The planner also reaches unseen goals, and the same recipe, with a planner trained per task, works for kicking and for pushing or pulling. The pipeline runs on a real Unitree G1 without real-world fine-tuning, with robot and object poses from motion capture. I trained some of the diffusion planner models and worked on tracker fine-tuning, the alternative that the paper compares DA:PPO planner fine-tuning against.
@misc{omar2026diplo,
  title         = {{DiPLO}: Self-distilled Diffusion Planning for Loco-manipulation},
  author        = {Omar, Shafeef and Sanokowski, Sebastian and Daneshmand, Elham and
                   Yu, Dian and Cremers, Daniel and Schmid, Cordelia and Khadiv, Majid},
  year          = {2026},
  eprint        = {2610.24847},
  archivePrefix = {arXiv},
  primaryClass  = {cs.RO},
  url           = {https://arxiv.org/abs/2610.24847}
}